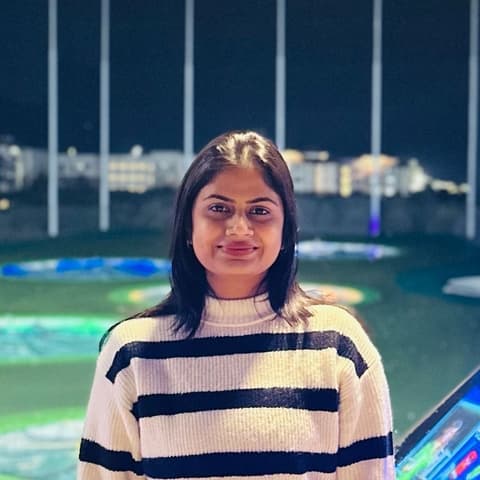
Bhavana Jagarlapudi
Verified Expert in Engineering
Data Engineer and Developer
Austin, TX, United States
Toptal member since September 22, 2025
Bhavana is a senior data engineer with over 8 years of experience building scalable cloud data solutions. She specializes in Azure Databricks, Azure Data Factory, PySpark, SQL, Delta Lake, Snowflake, and AWS. She has extensive experience designing ETL/ELT pipelines, modernizing data platforms, optimizing data processing, and delivering reliable data solutions for analytics, reporting, and business decision-making.
Portfolio
Experience
- SQL - 8 years
- Snowflake - 8 years
- Microsoft Power BI - 7 years
- Microsoft Azure - 6 years
- PySpark - 6 years
- Azure Databricks - 6 years
- ADF - 6 years
- Amazon Web Services (AWS) - 4 years
Preferred Environment
Microsoft Azure, PySpark, Azure Databricks, Amazon Web Services (AWS), Azure Data Factory (ADF), SQL, Databases, Microsoft Power BI, Python, Snowflake
The most amazing...
...project I've delivered modernized a legacy enterprise data platform into an Azure Databricks Lakehouse supporting company-wide financial reporting.
Work Experience
Databricks Engineer
Wegmans
- Managed the enterprise modernization initiative to migrate legacy EDW-based financial and operational reporting to an Azure Databricks Lakehouse integrated with SAP and Power BI.
- Designed and developed Silver and Gold data pipelines supporting enterprise inventory valuation, purchasing, cost accounting, financial reporting, profit and loss, income statement, and weekly reporting processes.
- Designed and developed end-to-end product data pipelines on Azure Databricks using the Medallion Architecture (Bronze, Silver, and Gold) to support enterprise analytics and reporting.
- Built scalable ingestion pipelines using Databricks Auto Loader (Managed File Events) and Delta Lake to process incremental product data with schema evolution.
- Developed Delta Live Tables (DLT) pipelines implementing Bronze, Silver Type 1, and Silver Type 2 data models using Auto CDC and SCD Type 1/Type 2 processing.
- Built PySpark and Databricks SQL transformations for nested JSON processing, data cleansing, standardization, deduplication, and business rule implementation.
- Managed Unity Catalog objects, service principals, environment configurations, permissions, and deployment strategies to enable secure, governed, and reliable multi-environment data platform releases.
- Automated deployments using Databricks Asset Bundles, GitHub Actions, and CI/CD pipelines across Development, Test, Preview, and Production environments.
- Performed production deployments, post-deployment validation, data reconciliation, and root cause analysis by comparing data across Bronze, Silver, Gold, and legacy datasets.
- Supported production incidents by investigating pipeline failures, validating data consistency, troubleshooting CDC and streaming issues, and coordinating fixes across engineering teams.
Senior Data Engineer
Otsuka America Pharmaceutical US
- Designed and implemented metadata-driven ingestion and transformation pipelines using Azure Databricks, ADLS, and Snowflake, improving processing efficiency by 40%.
- Developed parameterized, reusable Databricks workflows integrated with ADF and Airflow for automation and reliability in production environments.
- Implemented Delta Live Tables (DLT) pipelines for continuous ingestion and transformation, reducing manual orchestration overhead.
- Leveraged Autoloader with schema evolution to process high-volume datasets into Delta Lake.
- Implemented governance and security with Unity Catalog, Azure Purview, Key Vault, and RBAC, ensuring compliance with HIPAA and GDPR.
- Configured Databricks environments with Terraform and YAML, ensuring consistent multi-environment deployments (DEV/UAT/PROD).
- Integrated REST APIs within Databricks to enrich publisher and healthcare datasets with external reference and master data sources, ensuring accuracy and completeness.
- Optimized Spark jobs with partitioning, caching, and broadcast joins, reducing processing times by 35%.
- Delivered a centralized Snowflake hub to enable downstream reporting and advanced analytics through Power BI and data science teams.
- Developed PySpark-based transformation frameworks in Databricks to process large-scale publisher and healthcare datasets, enabling efficient joins, aggregations, and schema validations for downstream analytics.
Senior Data Engineer
Johnson & Johnson
- Built HIPAA-compliant ETL pipelines in Azure Databricks to ingest and process clinical trial, claims, and EHR datasets into Snowflake for unified analytics.
- Developed PySpark workflows to transform structured and semi-structured healthcare data (FHIR/HL7), ensuring interoperability and high-quality reporting.
- Designed scalable Snowflake data models to support analytics on patient outcomes, provider performance, and regulatory compliance metrics.
- Implemented Delta Live Tables (DLT) and Autoloader pipelines to automate ingestion of healthcare and claims datasets with schema evolution.
- Optimized Spark SQL jobs with partitioning, caching, clustering, and broadcast joins, improving performance for large-scale claims and clinical datasets.
- Integrated API-based data sources within Databricks to enrich claims and provider datasets with external reference and compliance data.
- Collaborated with finance and compliance teams on claims and reimbursement datasets, providing validated pipelines for regulatory and cost reporting.
- Configured governance and security using Azure Purview, RBAC, and encryption at rest/in transit, ensuring HIPAA and GDPR compliance.
Cloud Data Engineer
Capital One Financial
- Built ETL pipelines using AWS Glue and Lambda to ingest and transform enterprise data from on-premises and cloud sources into Amazon Redshift and Neptune.
- Migrated a legacy on-premises warehouse into Amazon Redshift, collaborating on schema design while implementing automated ingestion workflows and performance-optimized load strategies.
- Integrated data into Amazon Neptune by preparing graph-friendly datasets and supporting bulk loads, enabling analysis of dependencies, hierarchies, and fraud detection use cases.
- Developed pipelines to export Neptune graph insights back into Redshift, ensuring seamless integration of graph analytics with relational reporting and BI dashboards.
Cloud Engineer
LTIMindtree
- Built ETL workflows using SQL Server Integration Services (SSIS) to integrate data from heterogeneous sources into SQL Server.
- Optimized SQL and PL/SQL queries, improving data processing and report generation speed.
- Delivered high-quality documentation, including ER diagrams, functional workflows, and data dictionaries.
Experience
Enterprise Financial Reporting Modernization
Enterprise Product Data Platform
Data Harmonization Framework (DHF) Project
I leveraged Delta Lake for incremental loads and ACID transactions, while implementing Spark optimizations such as partitioning, caching, and Z-ORDER to improve performance by 40% and reduce reporting latency by 80%. To ensure compliance, I enforced data governance with Azure Purview, Role-based Access Control (RBAC), and Azure Key Vault. This project delivered a secure and scalable foundation that enabled faster insights and supported Microsoft Power BI dashboards for business users.
Skills
Libraries/APIs
PySpark
Tools
Git, AWS Glue, Spark SQL, Microsoft Power BI, Amazon Athena, Tableau, GitHub, Looker, AWS Step Functions, Erwin, Amazon Virtual Private Cloud (VPC), AWS IAM, Terraform
Languages
SQL, Snowflake, Python, Python 3, Java, Scala
Frameworks
ADF, Spark, Delta Live Tables (DLT), Apache Spark
Paradigms
HIPAA Compliance, ETL, Role-based Access Control (RBAC), Agile
Platforms
Azure Data Lake Storage, Azure, Databricks, Amazon Web Services (AWS), Docker, Azure Synapse, Amazon EC2, Oracle, AWS Lambda, Apache Kafka
Storage
PostgreSQL, Data Pipelines, Amazon S3 (AWS S3), Redshift, PL/SQL, SQL Server 7, Teradata, SQL Server Integration Services (SSIS), SQL Server Reporting Services (SSRS), Databases
Industry Expertise
Healthcare
Other
Azure Databricks, Delta Lake, Data Modeling, Azure Data Lake, Microsoft Azure, Data Engineering, Data Analysis, Amazon Redshift, CI/CD Pipelines, Amazon Neptune, Data Build Tool (dbt), Azure Data Factory (ADF), Microsoft Purview, event grid, Fivetran, AWS CodePipeline, Excel 365, Data Warehousing, Amazon RDS, Azure Data Lake Storage (ADLS Gen2), Databricks Auto Loader, Medallion Architecture, GitHub Actions, Databricks Asset Bundles (DAB), Azure Event Grid, DAB
How to Work with Toptal
Toptal matches you directly with global industry experts from our network in hours—not weeks or months.
Share your needs
Choose your talent
Start your risk-free talent trial
Top talent is in high demand.
Start hiring