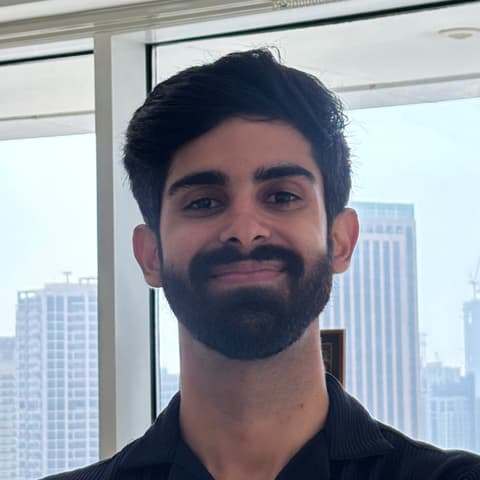
Bhavi Chawla
Verified Expert in Engineering

Data Scientist and Developer
Dubai, United Arab Emirates
Toptal member since September 3, 2026
Bhavi is a senior data scientist with 6+ years of experience in the eCommerce and pharmaceutical sectors, specializing in recommendations, search ranking, ads, cross-sell, churn, and uplift/causal inference. He builds and rigorously evaluates ML systems, from Transformer-based models to multi-armed bandits, translating statistical insights into business impact. Bhavi has open-sourced Moo-GBT and published research on cross-domain recommendations at CODS COMAD 2024.
Portfolio
Experience
- Deep Learning - 8 years
- Machine Learning - 8 years
- Feature Engineering - 6 years
- Predictive Modeling - 6 years
- Recommendation Systems - 5 years
- Contextual Bandits - 3 years
- Advertising Technology (Adtech) - 3 years
- Uplift Modeling - 2 years
Work Experience
Senior Data Scientist
Careem
- Designed and evaluated end-to-end uplift and predictive models, assessing model accuracy, statistical validity, and methodological soundness across user reactivation campaigns, improving CLTV/CAC ratio by 8%.
- Built and validated churn prediction models, rigorously evaluating model performance using precision/recall, lift curves, and business metrics, driving a 6.5% reduction in churn.
- Developed an end-to-end experimentation and evaluation framework combining uplift modeling and A/B testing, assessing incremental lift and ensuring methodological rigor across campaigns, increasing marketing efficacy.
- Directed cross-domain personalization model development, evaluating model outputs, comparing approaches, and assessing reasoning quality to improve cross-sell conversion by 7% and contribute approximately 3.2% incremental contribution margin.
- Drove homepage personalization and widget ranking using multi-armed bandit algorithms, continuously evaluating model outputs and performance metrics, driving a 10% improvement in contribution margin and a 5% uplift in vertical conversion rate.
- Spearheaded cross-functional alignment across product, growth, marketing, and engineering teams, standardizing ML deployment workflows and reducing model production time across multiple initiatives.
Data Scientist II
Swiggy
- Developed and evaluated recommendation ML systems, assessing feature engineering pipelines, user embeddings, learning-to-rank models, contextual bandits, and sequence models for accuracy and production quality.
- Productionized a contextual multi-armed bandit ranking algorithm, iteratively evaluating model outputs, identifying edge cases, and improving performance for ad recommendations on Swiggy's homepage.
- Applied transformer-based neural architectures to model user purchase history as sequences, evaluating model outputs against ground truth and iterating on architecture and feature choices to improve recommendation quality.
- Open-sourced Moo-GBT, a multi-objective optimized GBT framework, building and documenting a reusable, production-grade ML library.
- Published research on a cross-domain recommender system for cold-start personalization, applying rigorous experimental design and evaluation methodology, and was accepted at CODS COMAD 2024.
- Built a simulation-based ROI forecasting model, applying statistical modeling, scenario analysis, and sensitivity testing to validate outputs and ensure analytical accuracy.
- Delivered personalized push notification recommendations for millions of users, evaluating bandit algorithm performance, identifying inconsistencies, and improving real-time decisioning quality.
Data Science Associate
ZS Associates
- Architected large-scale supervised ML classification models for a pharma client, processing 1+ billion rows of longitudinal medical claims data and validating model outputs for accuracy, generalisability, and edge cases.
- Built a sequential predictive model for patient drug-switching behavior, applying time-series analysis and statistical validation to assess model performance against business objectives.
- Designed an AutoML tool for automated feature engineering on longitudinal data using genetic algorithms that is applicable to any regression or classification task, with built-in evaluation and benchmarking of generated features.
Project History
Library for Multi-objective Optimization in Gradient-boosted Trees
https://github.com/Swiggy/Moo-GBTEducation
Bachelor's Degree in Computer Science and Engineering with Specialization in AI/ML
Indian Institute of Information Technology, Sri City - Sri City, India
Skills
Libraries/APIs
Pandas, NumPy, Scikit-learn, XGBoost, TensorFlow, Keras, PyTorch, PySpark
Tools
AutoML, Amazon SageMaker, GitHub
Languages
Python, SQL, Scala, C, C++, JavaScript
Frameworks
Spark, Hadoop
Platforms
Databricks
Storage
Amazon DynamoDB, Redis
Other
Machine Learning, Statistics, Experimental Design, Communication, Attention to Detail, Code Review, Screeners, Written Communication, Artificial Intelligence (AI), Interviewing, Data Analysis, Data Engineering, Optical Character Recognition (OCR), Data Science, Causal Inference, Regression, Classification, Hypothesis Testing, Team Leadership, Team Management, System Architecture, Training, A/B Testing, Recommendation Systems, Feature Engineering, Contextual Bandits, Genetic Algorithms, Deep Learning, Reinforcement Learning, Data Mining, Information Retrieval, Algorithms, EMR, Clustering, Natural Language Processing (NLP), Large Language Models (LLMs), Uplift Modeling, Predictive Modeling, Personalization, Advertising Technology (Adtech), Crypto
How to Work with Toptal
Toptal matches you directly with global industry experts from our network in hours—not weeks or months.
Share your needs
Choose your talent
Start your risk-free talent trial
Top talent is in high demand.
Start hiring