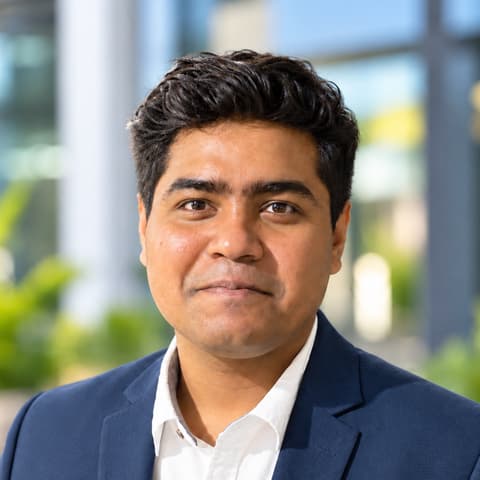
Raj Babu Das
Verified Expert in Engineering
Software Engineer and Developer
Bengaluru, Karnataka, India
Toptal member since September 28, 2026
Raj is a staff software and site reliability engineer with over 7 years of experience building and operating cloud-native platforms, distributed systems, and Kubernetes infrastructure for clients including Harness, ChaosNative, and MayaData. His expertise spans Go, Kubernetes, AWS, GCP, Terraform, Helm, and observability. At Harness, Raj reduced infrastructure costs by $100,000 annually.
Portfolio
Experience
- DevOps - 8 years
- Monitoring & Alerting - 7 years
- Go - 7 years
- Prometheus - 7 years
- Incident Management - 7 years
- CI/CD Pipelines - 7 years
- Site Reliability Engineering (SRE) - 7 years
- Kubernetes - 7 years
Preferred Environment
Kubernetes, Terraform, Helm, CI/CD Pipelines, Go, Prometheus, Azure, Amazon Web Services (AWS), DevOps, Linux, Bash
The most amazing...
...platform I’ve built is a multitenant managed Prometheus platform from 0 to 1, achieving 99.9% uptime and saving $100,000 annually.
Work Experience
Staff Software Engineer
Harness
- Designed an internal LLM chat service on Kubernetes for an air-gapped network, with the control plane on a private cloud VM and vLLM serving the model on a dedicated NVIDIA GPU worker.
- Extended observability tooling with Prometheus, Grafana, and OpenTelemetry for the AI SRE and Chaos Engineering teams, improving platform reliability and developer productivity.
- Designed and built Harness Managed Prometheus-as-a-Service from 0 to 1, architecting a multi-tenant, enterprise-grade platform and automating its end-to-end lifecycle in collaboration with Product and SRE teams.
- Built a monitoring agent on top of Prometheus that collects metrics from each customer and tenant and ships them to the Harness Managed Prometheus Service.
- Reduced infrastructure costs by $100,000 annually through AI-driven infrastructure optimizations at Harness.
- Deployed and operated applications on the Harness self-managed platform in air-gapped environments, managing Kubernetes-based infrastructure and deployment workflows for restricted-network environments.
- Architected AI-Native incident management systems as part of the AI SRE module to speed up on-call response and reduce time-to-resolution.
- Designed and operated scalable Go microservices on Kubernetes. automated infrastructure provisioning end-to-end with Terraform and Helm.
Senior Software Engineer 2
Harness
- Provided technical leadership to a 10-engineer team during the integration of Chaos Engineering into the Harness platform, achieving product availability and first sales within 8 months.
- Promoted to staff engineer within one year based on technical leadership through general availability and the acquisition transition.
- Increased Chaos Engineering Module uptime to 99.9% by enhancing reliability in monitoring, response, and operations.
- Recognized as the best performer for 2 consecutive quarters for engineering impact and delivery.
Founding Engineer
ChaosNative (acquired by Harness)
- Joined as the first engineering hire and owned the architecture, back end, deployment, and infrastructure for the company's production platform from the ground up.
- Managed production infrastructure and release pipelines, ensuring cost-efficiency without DevOps support.
- Selected and operated MongoDB and Redis as the primary datastores during development, using MongoDB for core application data and Redis as the caching layer.
- Provided technical leadership to a small team of engineers to deliver scalable, cost-efficient production systems as the company scaled.
- Developed microservices in Go with Kubernetes-native architecture.
- Led engineering contributions to LitmusChaos, a CNCF chaos engineering project, helping advance it from CNCF Sandbox to the incubation stage.
Software Engineer
MayaData (acquired by DataCore)
- Contributed to back-end microservices in Go for cloud-native data and chaos engineering platforms, covering feature development, bug fixes, and code reviews.
- Migrated the company's on-prem GitLab instance (50+ repositories) and CI pipeline from GCP to AWS with near-zero downtime, including a DNS cutover measured in milliseconds, using Velero for backup and restore.
- Participated in on-call rotations and supported SRE practices, triaging production incidents on Kubernetes workloads.
- Built Prometheus and Grafana dashboards and configured alerting to improve visibility into service health, reducing mean time to resolution (MTTR) for production incidents.
Experience
LLM Deployment on Azure and a GPU Node
https://github.com/imrajdas/llm-deploymentThe two machines do not share a network, and Azure's public IP is only a NAT address, so I linked them with WireGuard and ran the pod network over that tunnel. On the GPU node, I installed the NVIDIA Container Toolkit, scheduled vLLM with a Kubernetes RuntimeClass and a GPU label, and mounted the model weights on a local volume. Pausing the GPU VM stops compute billing and keeps the downloaded weights.
I wrote the setup, pause, and resume flow, and laptop access to the cluster through an SSH tunnel, with the Kubernetes API left off the public internet.
MCP Gateway
https://github.com/mcpHQ/mcp-gatewayI architected and developed the gateway as a Go service supporting both HTTP and stdio transports, with upstream authentication via API keys, bearer tokens, JWT, and Basic Auth, including environment-variable-based secret interpolation.
It provides scoped endpoints such as /mcp/dev-tools, endpoint-level rate limiting, API key-to-endpoint mapping, usage counters, audit logging, tool-name namespacing, and persistent tool discovery using SQLite with embedded migrations. I also built the spec-first OpenAPI admin API and embedded Preact-based admin UI, and delivered multi-architecture Docker images and a Helm chart for Kubernetes deployments with persistent storage.
The gateway implements the MCP JSON-RPC lifecycle (initialize, tools/list, and tools/call) and persists discovered tool catalogs across restarts, providing a consistent and centrally governed interface for MCP clients.
LitmusChaos
https://litmuschaos.ioI started by writing chaos experiments and the Kubernetes jobs that run them: disk loss on AWS and OpenEBS, CoreDNS pod delete, and OpenEBS pool network loss, network delay, and control-plane pod delete. I converted several pumba DaemonSets into node-selected Jobs, and added Ansible lint and Trivy checks to the experiment pipeline.
On the platform, I worked on the path from ChaosCenter to a target cluster. That includes event tracking for Litmus 3.x, moving cluster credentials into agent Secrets, node selectors and tolerations on the delegate manifest, readiness probes for the GraphQL and auth servers, security contexts with a read-only root filesystem, and an unprivileged nginx image for the dashboard. I also tightened environment-variable handling in the GraphQL server and fixed the GitOps path in the event tracker.
Across the LitmusChaos organization, I have 399 merged pull requests, including 250 on litmuschaos/litmus.
Google Summer of Code 2020: Prometheus
https://summerofcode.withgoogle.com/archive/2020/projects/4546170073907200I worked extensively with Go, Kubernetes, Prometheus, KIND, AWS/EKS, Grafana, and open-source CI/testing workflows.
LFX Mentorship, The Linux Foundation
https://mentorship.lfx.linuxfoundation.org/project/54adaade-8537-4150-b4ea-988454615ed7Education
Engineer's Degree in Computer Science and Engineering
Kalinga Institute of Industrial Technology - Bhubaneswar, India
Certifications
CNCF Ambassador
The Linux Foundation
PCA: Prometheus Certified Associate
The Linux Foundation
Speaker: KubeCon + CloudNativeCon Europe 2023
The Linux Foundation
Certified Kubernetes Administrator
The Linux Foundation
Skills
Libraries/APIs
Jenkins Pipeline, REST APIs, OpenAPI, vLLM
Tools
Terraform, Helm, Grafana, GitLab CI/CD, GitHub, Amazon EKS, Logging, Azure Kubernetes Service (AKS), AWS CloudFormation, AWS IAM, Amazon Virtual Private Cloud (VPC), AWS Cloud Development Kit (CDK), OpenTofu, CircleCI, GitLab, Jenkins, Vim Text Editor, Ansible, Claude Code, Velero
Languages
Go, Bash, HTML, Python, GraphQL
Paradigms
Microservices, DevOps, Azure DevOps, Continuous Delivery (CD), Continuous Integration (CI), Model Context Protocol (MCP)
Platforms
Kubernetes, Docker, MacOS, Azure, Amazon Web Services (AWS), Harness, Linux, Amazon EC2, Google Cloud Platform (GCP), Harbor, Cloud Native, OpenStack, OpenShift, Ollama
Storage
MongoDB, PostgreSQL, NoSQL, Redis, SQLite
Frameworks
Backstage
Other
Prometheus, OpenTelemetry, CI/CD Pipelines, Monitoring & Alerting, Incident Management, System Architecture, Site Reliability Engineering (SRE), Chaos Engineering, Cloud Cost Management, RESTFul APIs, Infrastructure as Code (IaC), Containerization, Deployment, Incident Response, Cloud Architecture, Cloud Infrastructure, Cost Reduction & Optimization (Cost-down), Architecture, API Gateways, Cloud Networking, API Management, Product Ownership, Cloud Engineering, Cloud Platforms, Virtual Cloud Network (VCN), APIs, Infrastructure, AWS Secrets Manager, Amazon RDS, Security Groups, Machine Learning Operations (MLOps), Microsoft Azure, Software Architecture, Monitoring, Technical Leadership, Observability, SigNoz, Argo CD, Open Policy Agent (OPA), AWS DevOps, Cloud, Pulumi, GitOps, AI Agents, Artificial Intelligence (AI), AI DevOps, Graphics Processing Unit (GPU), GPU Computing, Infrastructure Automation, Cost Optimization, System Design, Distributed Systems, Platform Engineering, Reliability Engineering, Team Mentorship, Cross-functional Collaboration, Kyverno, Computer Science, Cloud Computing, Cloud Native Computing Foundation (CNCF), Container Orchestration, Open Source, Thought Leadership, NVIDIA vGPU, LLM Agents
How to Work with Toptal
Toptal matches you directly with global industry experts from our network in hours—not weeks or months.
Share your needs
Choose your talent
Start your risk-free talent trial
Top talent is in high demand.
Start hiring