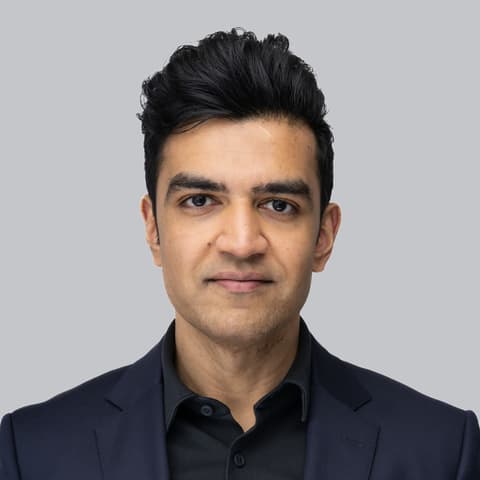
Suresh Kasipandy
Verified Expert in Engineering
Data Scientist and Developer
Toronto, ON, Canada
Toptal member since August 30, 2021
Part data scientist and part cloud solutions architect, Suresh excels at taking business problems and setting up end-to-end cloud data systems to solve them. Ranging from streaming data pipelines to data lakes to deep learning systems, Suresh leverages the latest tech and cutting-edge approaches to build robust and fault-tolerant systems that help you leverage business value from your data.
Portfolio
Experience
- SQL - 6 years
- Data Science - 6 years
- Machine Learning - 5 years
- Python - 5 years
- Data Engineering - 4 years
- Amazon Web Services (AWS) - 4 years
- Generative Pre-trained Transformers (GPT) - 3 years
- TensorFlow - 3 years
Preferred Environment
Jupyter Notebook, MacOS, Linux, Python, TensorFlow
The most amazing...
...thing I've built is a recommendation system for a food ordering app, providing a unique and personalized UX to every user.
Work Experience
Senior Data Platform Engineer
RBC Global Asset Management
- Architected a multi-environment Azure Databricks lakehouse platform, enabling multiple data engineering teams, while developing.
- Built reusable Terraform IaC modules built on the Databricks Terraform provider and established internal infrastructure automation standards.
- Provisioned robust role-based access control mechanism leveraging data governance principles for Databricks components such as catalogs, schemas, and tables using Unity Catalog and Terraform.
- Provisioned and managed compute for Databricks, including SQL warehouse and clusters, using cluster policies and instance pools to control costs, availability, and scalability.
- Contributed to the design and operation of a cloud-native data platform on OpenShift and Kubernetes, supporting Spark, JupyterHub, and Airflow workloads for analytics and data engineering.
- Deployed and managed Starburst Enterprise (Trino) to enable federated SQL access across diverse enterprise data sources.
- Built and maintained CI/CD pipelines using GitHub Actions and Databricks Asset Bundles to automate infrastructure and platform deployments.
- Implemented secure, governed data access patterns across storage, compute, and analytics layers to support enterprise data platform usage.
- Collaborated with platform, data engineering, and architecture teams to deliver scalable analytics infrastructure and onboard new data workloads.
Data Engineer
Pfizer - PGS Operations Insights
- Designed and implemented end-to-end data pipeline systems.
- Contributed to data engineering and API development for several high-profile projects.
- Involved in data modeling in relational and graph data models for both warehousing and application usage.
- Led data engineering effort across several projects.
Data Scientist
Foodhub
- Built a Redshift data warehouse on AWS for analytics and reporting.
- Developed ETL workflows using Python, Apache Airflow, Apache Spark, and AWS Glue.
- Constructed a complete BI reporting suite using AWS QuickSight.
- Created a chatbot solution using BotXO to automate customer service interactions.
- Engineered streaming data pipelines from MySQL using AWS Kinesis and AWS Lambda.
- Deployed a streaming data lake solution using AWS Kinesis, Apache Spark, AWS S3 and Apache Hudi.
- Built a fraud detection system to detect and flag fraudulent orders.
- Validated the POC for Segment's customer data platform (CDP) by proving business value across several verticals, including marketing, development, and operations.
- Deployed an in-cart recommendation engine using association analysis built on AWS S3, AWS Lambda, Apache Spark, and AWS API Gateway.
- Installed a purchase history-based recommendation engine using NLP and graph technology built on AWS Neptune (a high-performance graph database), AWS S3, AWS Lambda, Apache Spark, and AWS API Gateway.
Web Developer
Chowmill, Inc.
- Designed and implemented a mobile app's front-end features in React Native, including the UI, scene navigations, and push notifications.
- Spearheaded the implementation of several features, including promo codes, address entries, and a payment flow.
- Implemented user activity tracking and event logging using Firebase.
- Made several UX improvements that contributed to a better user journey as evidenced by user activity tracking.
- Utilized Git, Bitbucket, and Jira to coordinate with the team on the implementation and release of new features.
- Identified, documented, and resoloved bugs and defects.
Data Analyst Intern
Triva Tek Systems
- Created scripts for preprocessing and cleaning data for ad-hoc analysis requests using Python.
- Built data models for new features based on requirements and business rules.
- Analyzed historical data and then created reports on insights and trends.
- Developed dashboards and KPI reports in Tableau to help business users monitor business efficiency.
Web Developer
Techguru
- Developed the UX and front ends for websites based on client requirements.
- Wrote database scripts as well as SQL stored procedures, functions, and triggers.
- Conducted a sentiment analysis of social media and digital marketing analysis for clients and recommended improvements based on KPIs to improve website traffic and accessibility.
- Wrote application-level code to interact with RESTful web APIs and web services using Ajax, JSON, XML, and jQuery.
Experience
Agent Observability
https://github.com/VoidAxiom/agent-observabilityThe headline capability: when a Claude Code session spawns N Codex children, those children appear as children of the session, not as disconnected traces, and each can be correlated to the task or ticket it was working on.
Transport: OTel Collector (Go binary). Stock otelcol-contrib receives OTLP, batches, redacts, retries, and writes to ClickHouse via the official exporter. No Rust was written.
Emitter: Python with auto-instrumentors. Leverages OpenAIInstrumentor().instrument() and equivalents, allowing spans to appear automatically.
Build approach: walking skeleton first. Every milestone enriches a working end-to-end prototype and never adds a missing layer to a system that does not yet run end to end.
LLM Evaluation Harness for MLE Research Tasks (SWE-bench-inspired)
https://github.com/VoidAxiom/factory-bench• Suite orchestration with bounded parallel fan-out (ThreadPoolExecutor), per-task and per-suite budgets (tokens/wall-clock/tool calls), live cost accounting against a configurable model-pricing table, and Markdown rollup reports by difficulty and domain.
• Multi-service sandboxes via Docker Compose: tasks can declare sidecars (e.g., PostgreSQL with healthchecks) on a private user-defined network, with SQL-based graders executing through the sandbox boundary.
• SQLite-backed run store with idempotent additive migrations: every run, suite run, and individual check result is queryable; the CLI provides run, suite run, show-run, and pricing show commands.
• Architecture-as-code with LikeC4: the .c4 model under docs/architecture/ is the source of truth, validated in CI, with lifecycle tags (shipped vs planned) rendered visually distinct. PNG diagrams in the README are exported deterministically from the model.
RAG Search and QA System with Hybrid Retrieval and Evaluation
https://github.com/VoidAxiom/rag-nqLLaVA for Sensors
https://github.com/VoidAxiom/llava-for-sensorsFood Delivery Fraud Detection Simulator
https://github.com/VoidAxiom/fraud-forecastPostgreSQL 12 (weekly partitioned by placed_at) and Redis 6 were used for hot and cold order storage, as well as feature serving.
The synthetic simulator sustained 50 orders per second and modeled 1 million users, 15,000 stores, 80,000 menu items, and 2,000 drivers across 10 weighted UK cities. It generated approximately 2% labeled fraud across seven patterns, including delayed chargebacks.
Fraud detection was powered by a TensorFlow 2.3, TFX 0.22, and XGBoost 1.2 ensemble, with FastAPI-based scoring (p99 <100ms), Streamlit monitoring, and weekly retraining.
Education
Master's Degree in Data Science
University of Southern California - Los Angeles, CA, United States
Bachelor's Degree in Computer Engineering
Caledonian College of Engineering - Muscat, Oman
Certifications
Databricks Certified Data Engineer Associate
Databricks
Senior Data Scientist (SDS)
Data Science Council of America (DASCA)
Skills
Libraries/APIs
TensorFlow, Scikit-learn, PySpark, Pandas, OpenCV, NumPy, React, REST APIs, PyTorch
Tools
Amazon QuickSight, Claude, Git, GitHub, Jira, Tableau, Apache Airflow, Amazon Elastic Container Service (ECS), Amazon Athena, Microsoft Excel, AWS Glue, Claude Code, Terraform, Codex, Docker Compose, Amazon EKS, You Only Look Once (YOLO), Amazon OpenSearch, Jupyter, ChatGPT
Languages
Python, SQL, Python 3, Cypher, Snowflake, Bash, Bash Script, JavaScript, XML, Swift, TypeScript
Paradigms
ETL, Business Intelligence (BI), DevOps, Automation, Unit Testing, Model Context Protocol (MCP), Testing
Platforms
Jupyter Notebook, Amazon Web Services (AWS), MacOS, Linux, Docker, AWS Lambda, Apache Hudi, Amazon EC2, Databricks, Kubernetes, Red Hat OpenShift
Storage
Data Pipelines, Graph Databases, Data Lakes, Redshift, Amazon S3 (AWS S3), MySQL, Neo4j, Databases, PostgreSQL, Data Integration, Database Architecture, JSON, Redis, ClickHouse
Frameworks
Spark, Apache Spark, LangGraph, Agentic Frameworks, Selenium, Data Lakehouse, Delta Live Tables (DLT)
Industry Expertise
Healthcare
Other
Data Science, Machine Learning, Data Mining, Natural Language Processing (NLP), Data Engineering, Data Analysis, Data Analytics, Generative Pre-trained Transformers (GPT), APIs, Unstructured Data Analysis, ETL Tools, Data Manipulation, Data Interpretation, Data Engineering, ETL Development, Stochastic Modeling, Organization, Time Series Analysis, Amazon Kinesis, Segment, Chatbots, Association Rule Learning, Recommendation Systems, Data Modeling, Data Strategy, GraphDB, Dashboards, Data Visualization, Big Data, Writing & Editing, Deep Learning, Convolutional Neural Networks (CNNs), Recurrent Neural Networks (RNNs), Data Reporting, Artificial Intelligence (AI), Customer Journey, User Journeys, Data Migration, Analytics, Reporting, Algorithms, NLU, Dashboard Development, K-nearest Neighbors (KNN), Data Cleaning, Forecasting, Python, SQL, Data Pipelines, Data Visualization, ETL, Data Wrangling, Data Analysis, Artificial Intelligence (AI), Machine Learning, Statistical Analysis, Large Language Models (LLMs), Architecture, Data Scientist, Marketing Analytics, AI Development, GitHub Actions, Back-end, FastAPI, Vector Databases, RESTFul APIs, Retrieval-augmented Generation (RAG), OpenAI, Feature Engineering, RAG Pipelines, AI Agents, Agentic AI, System Architecture, CI/CD Pipelines, Software Development Lifecycle (SDLC), Cursor AI, Agentic AI Systems, Data Warehousing, Machine Learning Operations (MLOps), Model Evaluation, Artificial Intelligence (AI), Large Language Models (LLMs), AI Product Strategy, AI Agent Orchestration, Cloud Infrastructure, Scripting, LLM Integration, Knowledge Graphs, LLM Reasoning, LangChain, Agentic RAG Systems, Conversational AI, Data Infrastructure, Security, AI Architecture, Optical Character Recognition (OCR), Monitoring, Telemetry, Agentic Coding, Web Dashboards, Qdrant, Orchestration, User Experience (UX), Amazon API Gateway, Causal Inference, Generative Artificial Intelligence (GenAI), Delta Lake, Production, NiFi, Solution Architecture, Disaster Recovery Plans (DRP), Amazon Web Services (AWS), Cloud, Unity Catalog, Data Quality, RAG Systems, RAG Architecture, Prompt Engineering, A/B Testing, Multimodal Models, Qwen, Observability, OpenTelemetry, DuckDB
How to Work with Toptal
Toptal matches you directly with global industry experts from our network in hours—not weeks or months.
Share your needs
Choose your talent
Start your risk-free talent trial
Top talent is in high demand.
Start hiring